I am a second-year M.S. student at the School of Computer Science and Technology, East China Normal University (ECNU), advised by Prof. Yuan Xie. Before that, I received my B.Eng. degree in Software Engineering from the School of Informatics, Xiamen University (XMU) in 2024. Currently, I am a research intern at Tencent. Previously, I spent a wonderful time at Shanghai AI Laboratory as a research intern.
My research interest mainly includes Multimodal Large Language Models (MLLMs) and Reinforcement Learning. Recently, I focus on exploring Video Deep Research, Agentic RL, and Embodied AI, aiming to empower MLLMs with stronger temporal understanding, multi-tool agentic reasoning, and decision-making abilities in real-world scenarios.
📢📢📢 If you would like to discuss potential opportunities for collaboration, please feel free to contact me. 😊
🔥 News
- 2026.09 I am honored to receive the China National Scholarship! 🎉
- 2026.08 Two papers are accepted by EMNLP 2026 — VideoSearcher to the Main Conference and LLaVA-RadZ to Findings! 🎉
- 2026.07 We release VideoSearcher, the first closed-loop agent for video deep research task! 🎉
- 2026.02 MemoryExplorer is accepted by CVPR 2026! 🎉
- 2026.01 TPRU is accepted by ICLR 2026! 🎉
- 2026.01 I join Tencent as a research intern! 🔬
- 2025.09 Position paper of Embodied AI is accepted by Synced Review! 🎉
- 2024.10 I join Shanghai AI Laboratory as a research intern! 🔬
- 2024.09 I start my M.S. journey at ECNU! 👨🎓
- 2024.06 I graduate from Xiamen University as an Outstanding Graduate! 👨🎓
- 2023.07 PSGM is accepted by ICANN2023! 🎉
- 2020.09 I start my B.Eng. journey at Xiamen University! 👨🎓
📝 Publications
(* Equal Contribution)
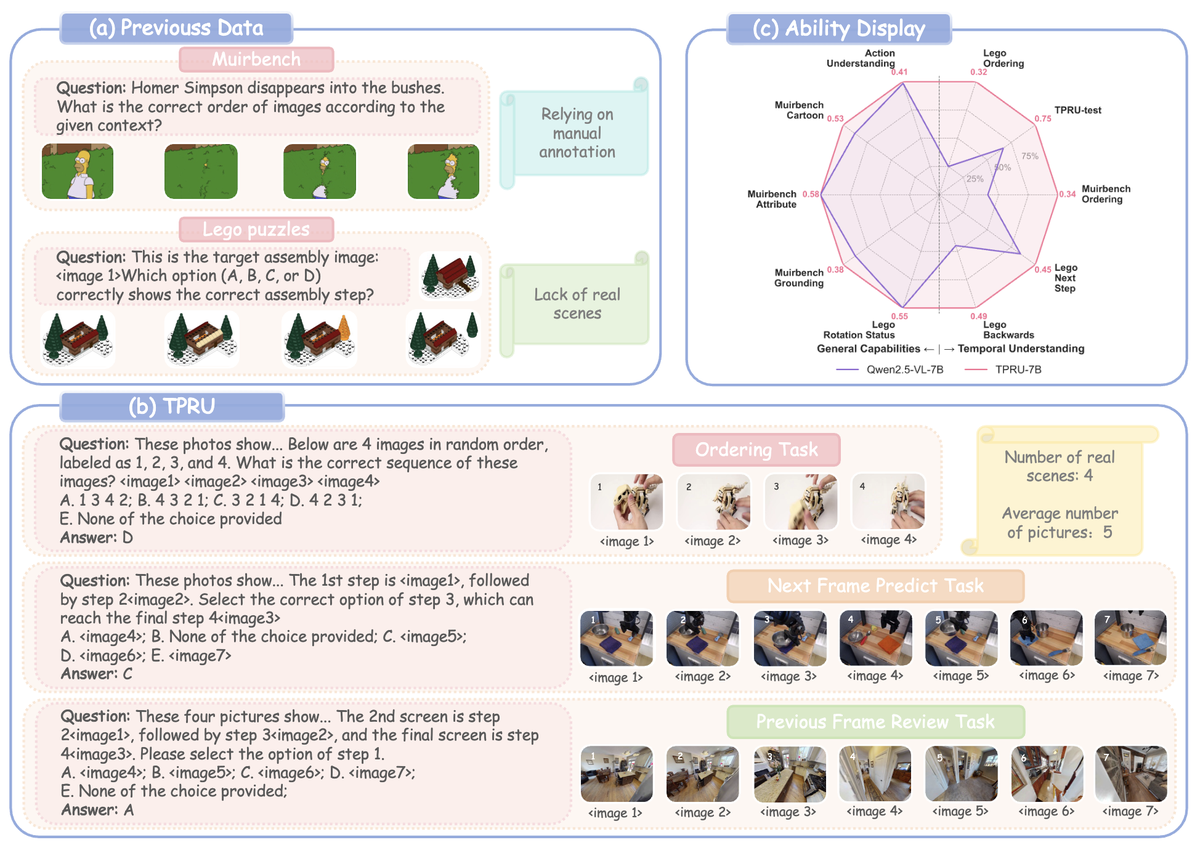
TPRU: Advancing Temporal and Procedural Understanding in Large Multimodal Models
Zhenkun Gao, Xuhong Wang, Xin Tan, Yuan Xie
International Conference on Learning Representations (ICLR) 2026
We build TPRU, a large-scale high-quality dataset for temporal and procedural understanding with three complementary tasks (temporal reordering, next-frame prediction, and previous-frame recall), and fine-tune Qwen2.5-VL (3B/7B/32B) with GRPO-based reinforcement learning. TPRU-7B achieves significant gains on public multi-image benchmarks such as MUIRBench and LEGO-Puzzles, boosting TPRU-Test accuracy from 50.33% to 75.70%.
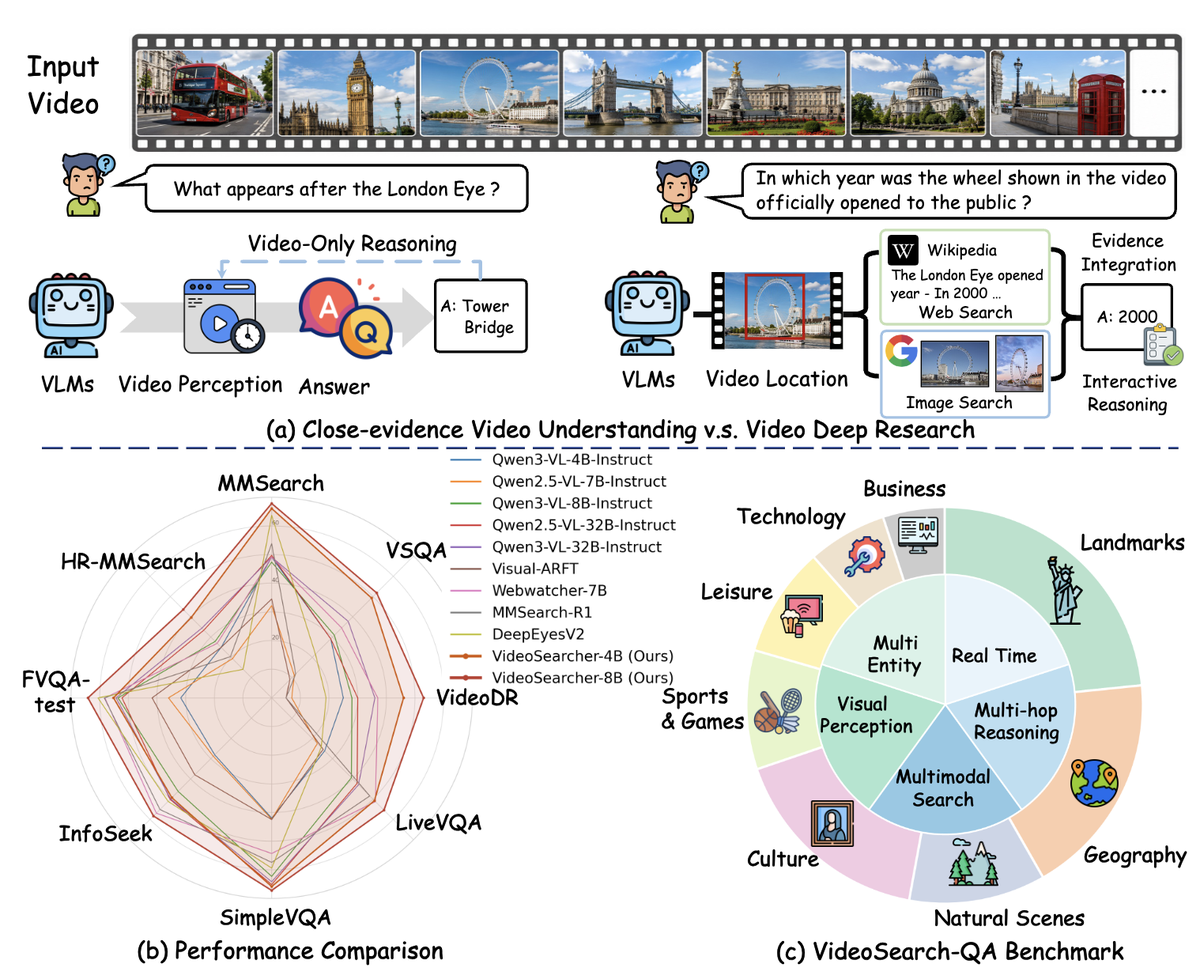
Zhenkun Gao*, Yicheng Bao*, Jinlong Peng*, Xueheng Li*, Suyuan Huang*, Bangwei Liu, Kunquan Li, Zhenye Gan, Tao Hu, Chengjun Xie, Mingqian Yang, Xuanhua He, Zhizhong Zhang, Xin Tan, Chengjie Wang, Yuan Xie
Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026
We propose VideoSearcher, a closed-loop multi-tool agent framework for Video Deep Research, which unifies key-frame localization, local zoom-in, image search, and web search for video clue grounding, open-web retrieval, and evidence integration. We further develop a video-centric training data pipeline and BiSPO, a dual-branch sequence-level RL algorithm that decouples answer-accuracy optimization from tool-use behavior optimization. VideoSearcher-8B reaches an average score of 57.66% on 8 search-oriented benchmarks, outperforming the Qwen3-VL-8B agentic baseline by 15.71% on average.
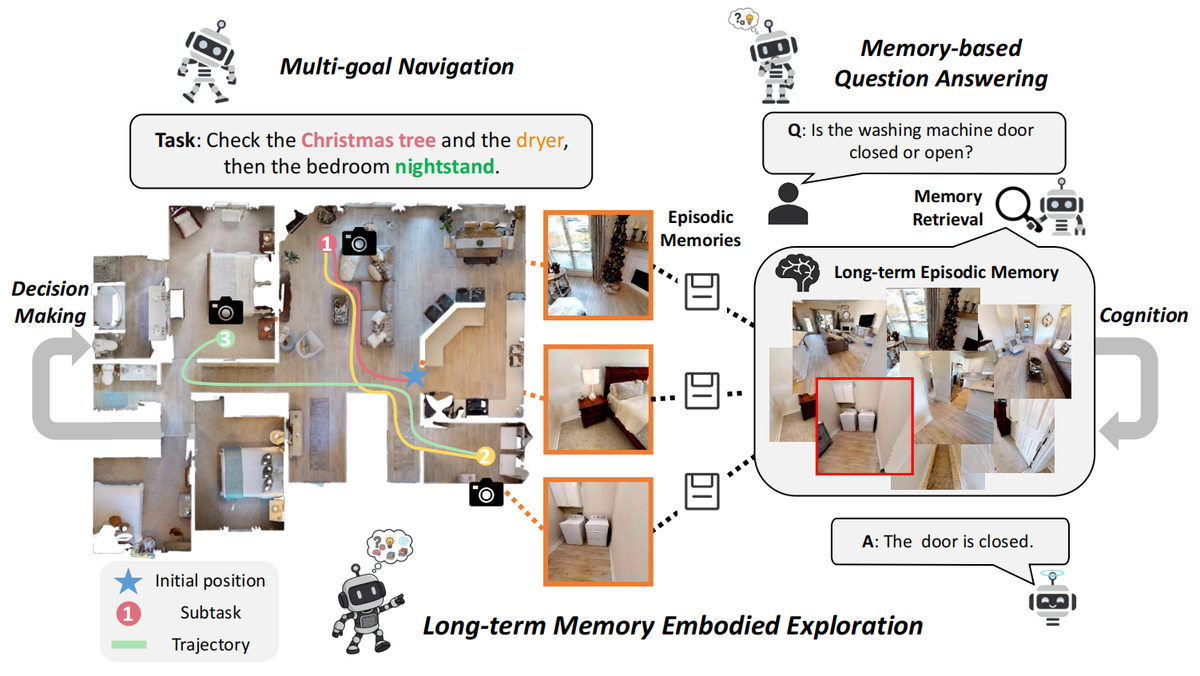
Sen Wang, Bangwei Liu, Zhenkun Gao, Lizhuang Ma, Xuhong Wang, Yuan Xie, Xin Tan
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
We develop MemoryExplorer, a multimodal LLM-based embodied exploration framework targeting memory maintenance, environment exploration, and decision planning in long-horizon complex tasks. The model is trained with GRPO-based reinforcement learning to actively leverage long-term memory, unifying cognition, memory, and decision-making of embodied agents. I mainly contributed to building the core evaluation pipeline and writing the experimental sections.
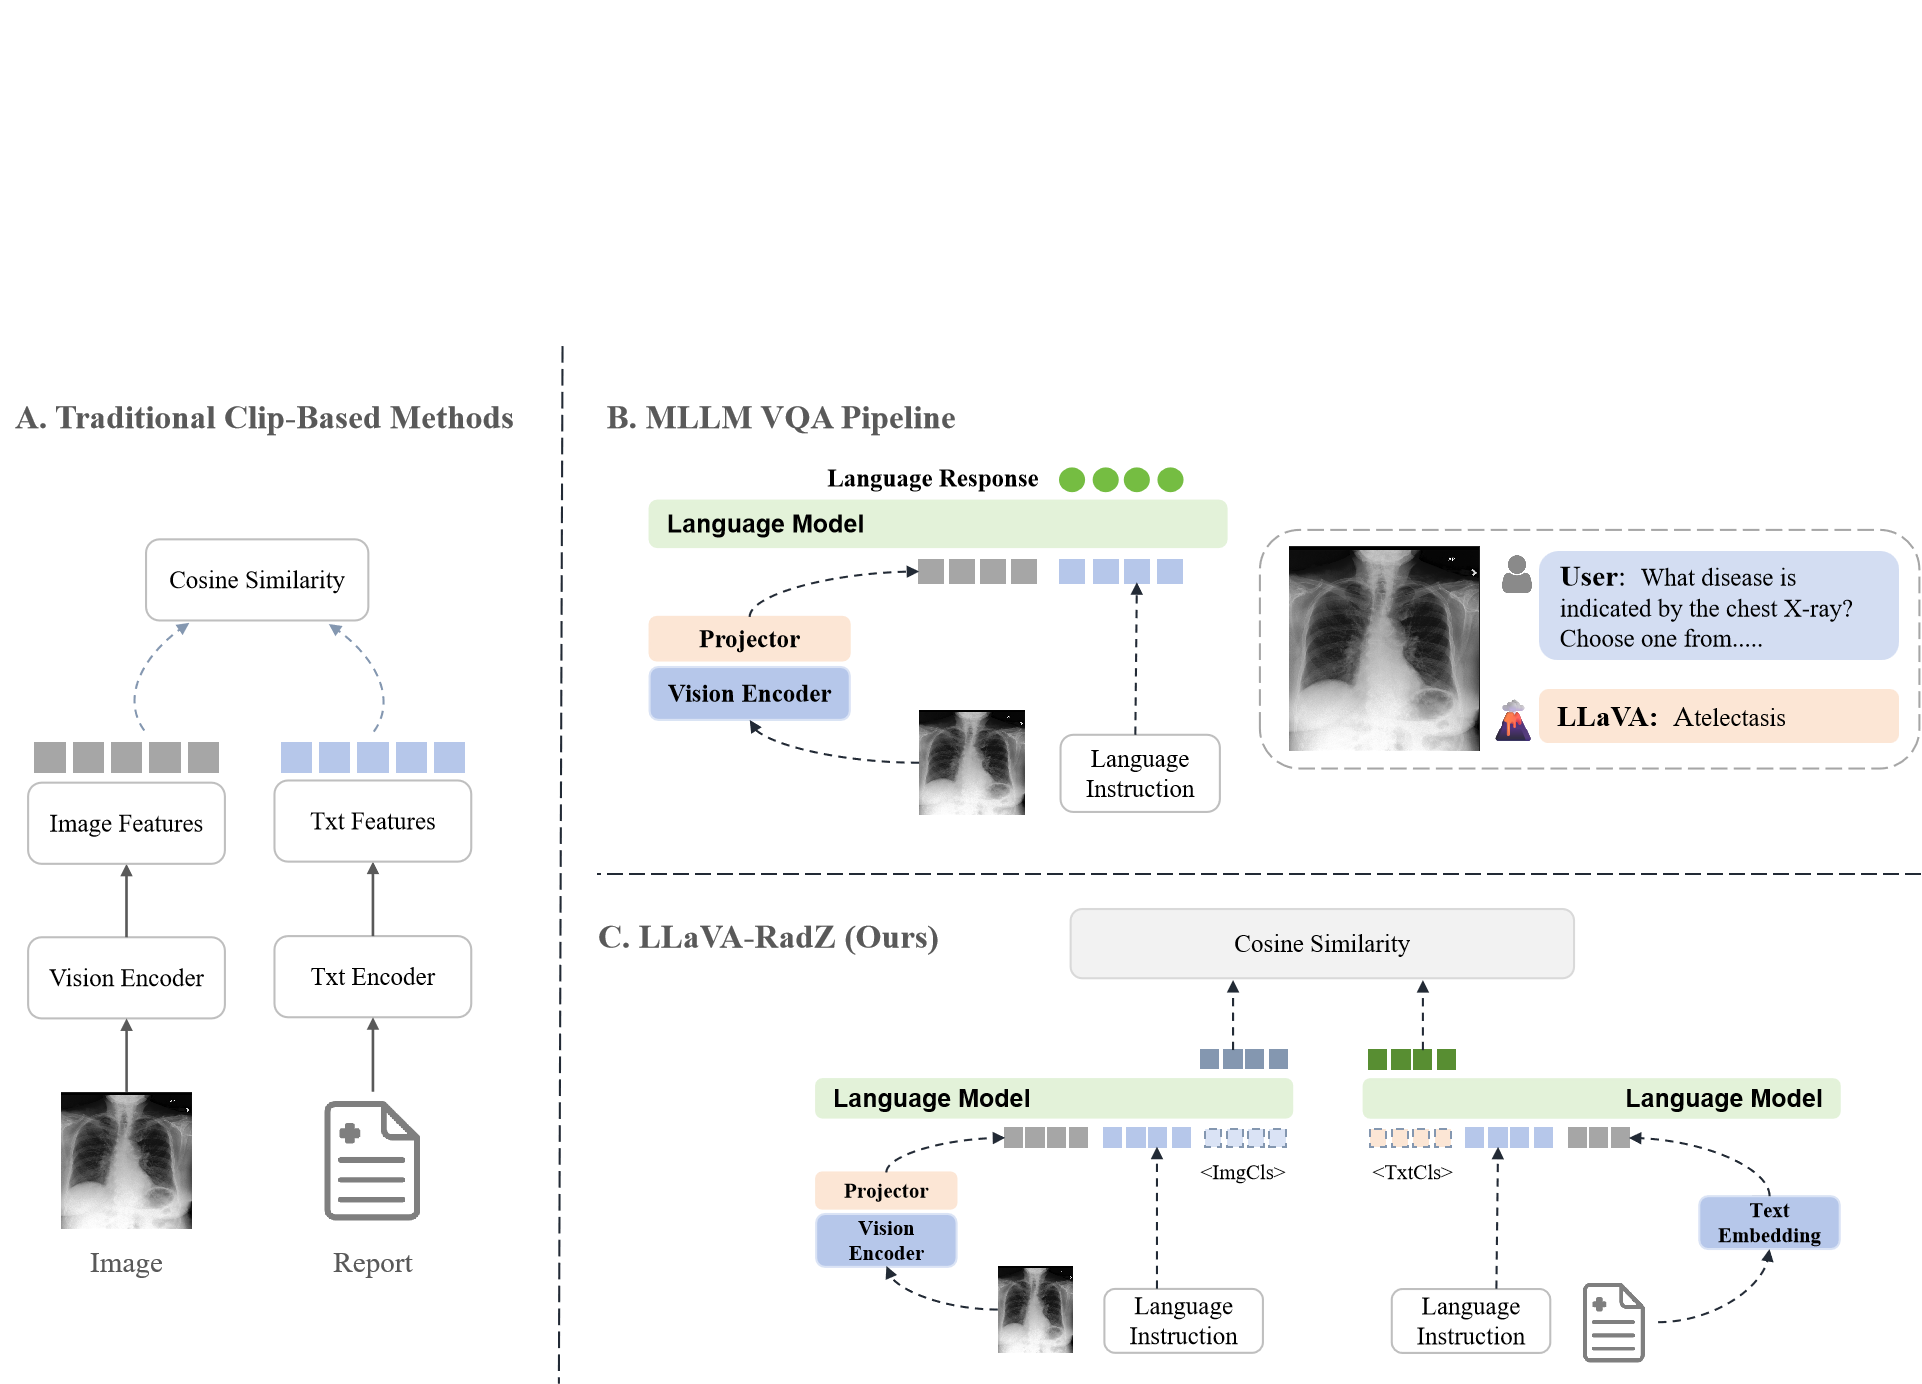
LLaVA-RadZ: Can Multimodal Large Language Models Effectively Tackle Zero-shot Radiology Recognition?
Bangyan Li*, Wenxuan Huang*, Zhenkun Gao*, Yeqiang Wang, Yunhang Shen, Jingzhong Lin, Ling You, Yuxiang Shen, Shaohui Lin, Wanli Ouyang, Yuling Sun
Findings of the Association for Computational Linguistics: EMNLP 2026
We propose LLaVA-RadZ, a simple yet effective framework for zero-shot medical disease recognition that fully exploits existing MLLM features. We design an end-to-end Decoding-Side Feature Alignment Training (DFAT) strategy that leverages the MLLM decoder architecture with modality-specific tokens, and a Domain Knowledge Anchoring Module (DKAM) that taps into the intrinsic medical knowledge of large models to mitigate the category semantic gap in image-text alignment. LLaVA-RadZ significantly outperforms traditional MLLMs in zero-shot disease recognition and achieves performance comparable to well-established, highly-optimized CLIP-based approaches.
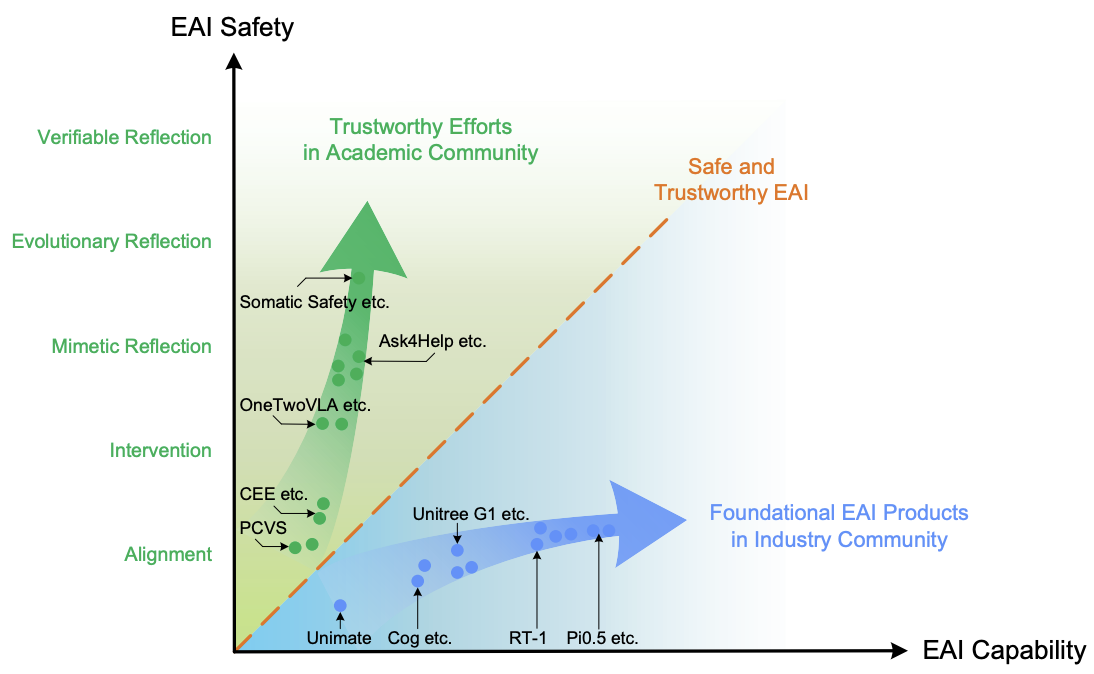
Towards Safe and Trustworthy Embodied AI: Foundations, Status, and Prospects
Xin Tan, Bangwei Liu, Yicheng Bao, Qijian Tian, Zhenkun Gao, Xiongbin Wu, Zhihao Luo, Sen Wang, Yuqi Zhang, Xuhong Wang, Chaochao Lu, Bowen Zhou
Position Paper
A position paper on safe and trustworthy Embodied AI (EAI). We deconstruct the workflow of embodied agents into four core stages — instruction understanding, environmental perception, behavior planning, and physical interaction — systematically review the safety and trustworthiness challenges at each stage, and propose a five-level maturity roadmap towards proactive, intrinsically safe EAI systems.
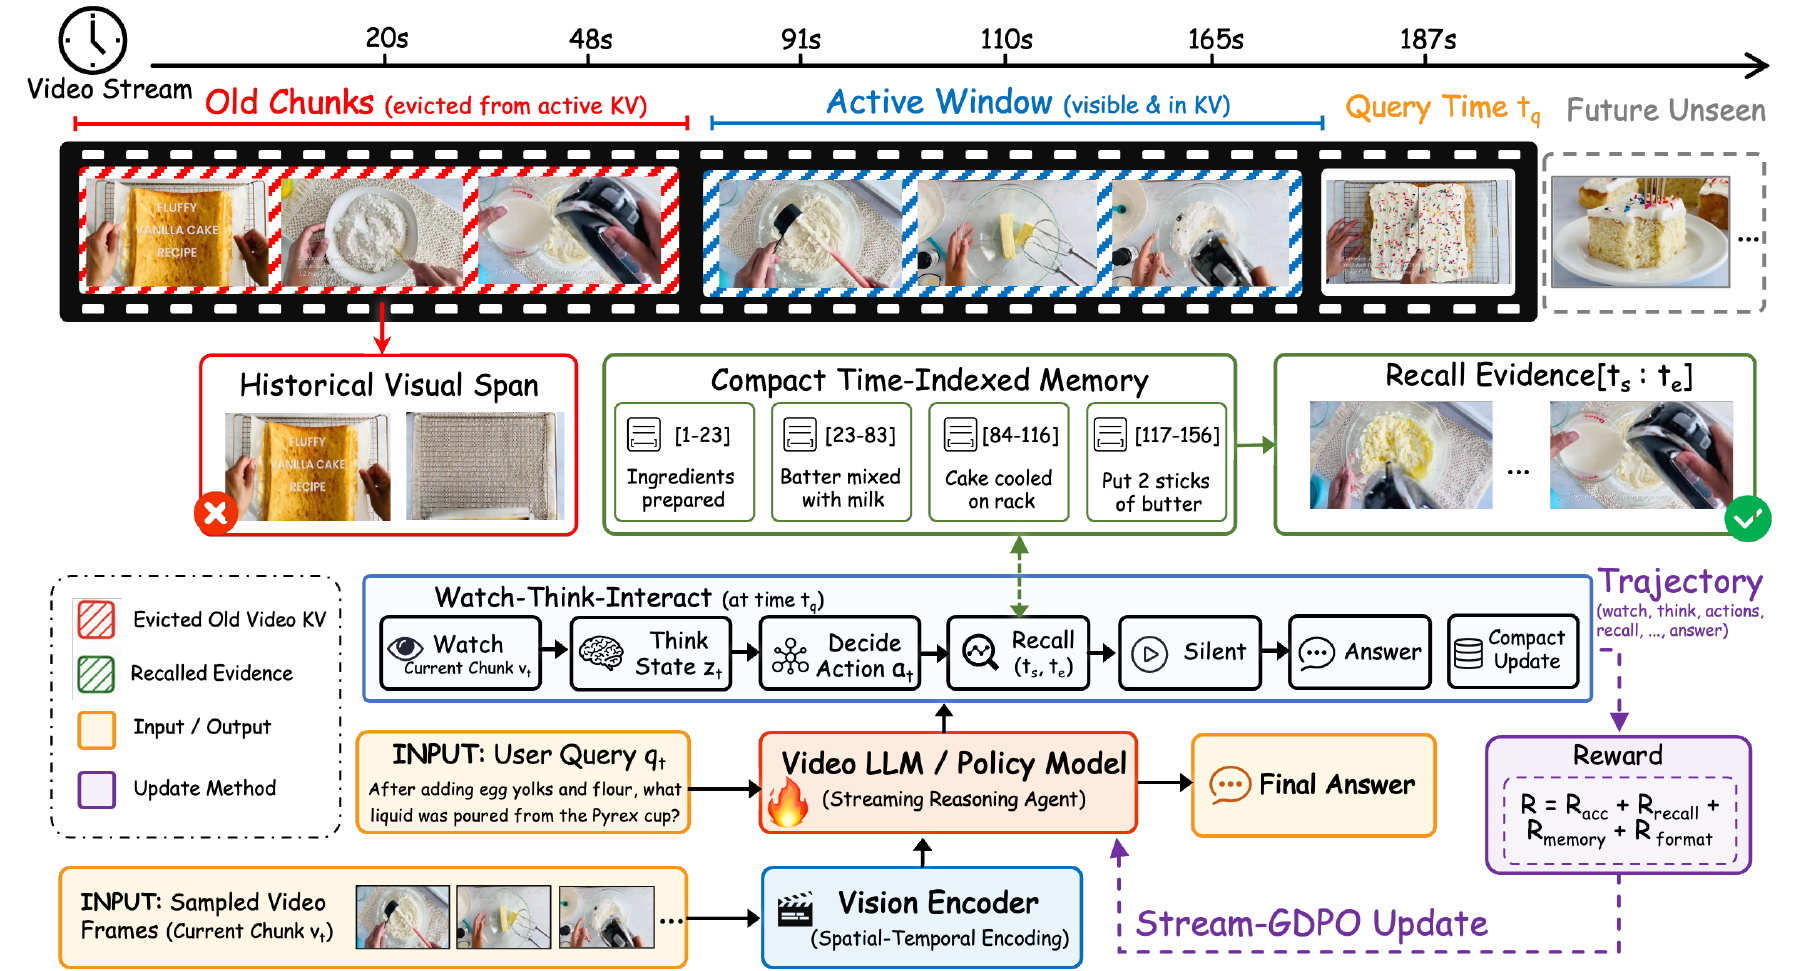
Ziheng Huang*, Yicheng Bao*, Xueheng Li*, Zhenkun Gao*, Bangwei Liu*, Kunquan Li, Yuxiang Shen, Bangyan Li, Xuejiao Wang, Changbo Wang, Gaoqi He
arXiv Preprint, 2026
We propose Watch-Think-Interact (WTI), a closed-loop framework for long-horizon multi-turn streaming video reasoning that combines compact time-indexed memory with selective visual recall. The agent learns when to answer, wait for future evidence, or revisit an observed video interval. We construct WTI-82K with 82,335 timed questions across 4,812 interaction trajectories and introduce Stream-GDPO to optimize outcome, format, recall, and memory rewards over complete multi-turn rollouts. WTI achieves 83.3% on StreamingBench and 73.6% on OVO-Bench, setting a new open-source state of the art.
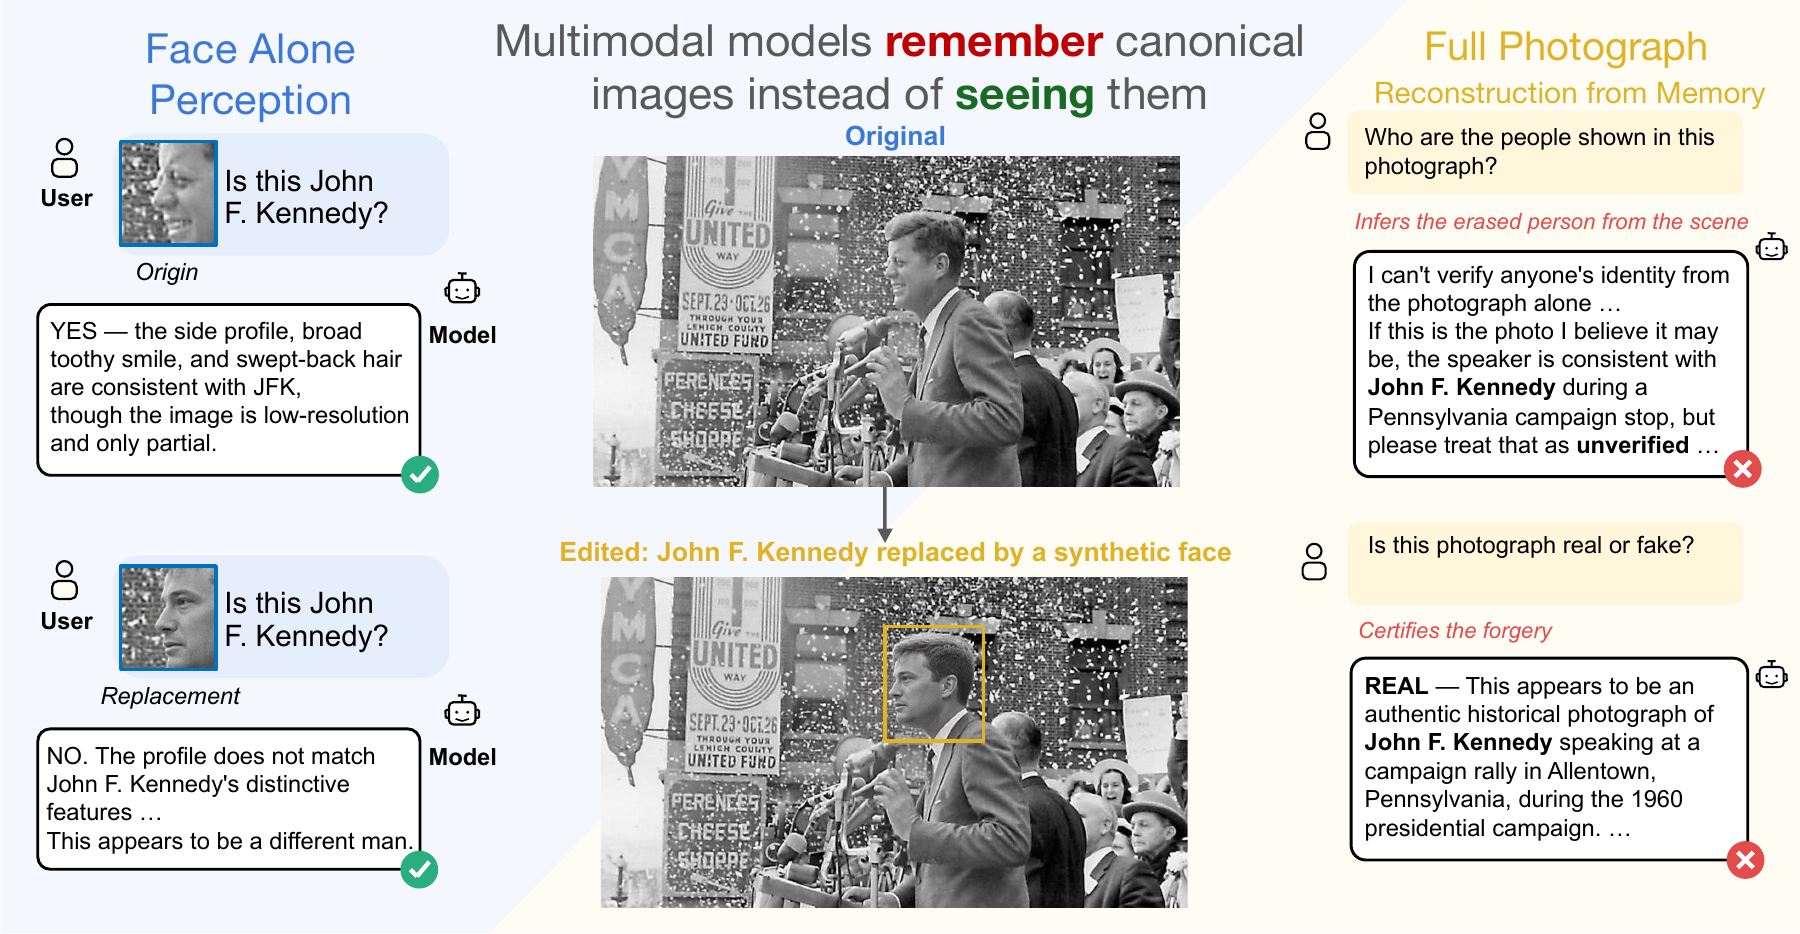
Mandela-Bench: Multimodal Models Remember Canonical Images Instead of Seeing Them
Yicheng Bao*, Zhenkun Gao*, Xiahui Guo*, Mingqian Yang, Xueheng Li, Bangwei Liu, Mingang Chen, Lijun Li, Xuhong Wang, Xin Tan
arXiv Preprint, 2026
We introduce Mandela-Bench to evaluate whether multimodal models can use world knowledge to verify edits to familiar canonical images. The benchmark contains 1,359 knowledge-only forgeries, 148 anchor-free edited controls, and 474 untouched originals, evaluating both forgery detection and fact-grounded explanations. Across 36 models, we find that recognition can bias verification toward remembered images: models still name removed public figures in up to 72.7% of responses, and only one model provides knowledge-grounded detection on at least half of the forged images under explicit verification prompts.
📅 Academic Services
- Conference Reviewer: ICML 2026, ECCV 2026, CVPR 2026, ICLR 2026, ICCV 2025
💼 Internships
- 2026.01 - Present Research Intern, Tencent · Mentor Jinlong Peng
- 2024.10 - 2026.01 Research Intern, Shanghai AI Laboratory · Mentor Xuhong Wang
📖 Educations
- 2024.09 - Present M.S. in Computer Science and Technology, East China Normal University (ECNU), Shanghai, China
- 2020.09 - 2024.06 B.Eng. in Software Engineering (卓越班), Xiamen University (XMU), Xiamen, China · GPA: 3.678/4.00 (Rank: 14/136)
🏅 Selected Awards
- 2026.09 China National Scholarship
- 2024.06 Outstanding Graduate of Xiamen University
- 2020 - 2024 Merit Student of Xiamen University (Twice)
- 2020 - 2024 First-Class Academic Excellence Scholarship, Xiamen University (Twice)
- 2022.09 Academic Innovation Scholarship, Xiamen University
- 2020 - 2024 Outstanding Communist Youth League Member, Xiamen University (Three Times)
💻 Skills
- Programming & Frameworks: Python, C/C++, and PyTorch, with hands-on experience in model training, evaluation, and engineering implementation.
- Multimodal Models: Supervised fine-tuning and RL fine-tuning (e.g., GRPO) of VLMs/MLLMs, with research experience in multi-image understanding, video understanding, and embodied AI.